DeepSeek-V3 Emerges as a Game-Changer in AI Development
In today’s increasingly competitive AI landscape, Chinese AI company DeepSeek has made a remarkable entrance. On December 26th, they officially launched their latest AI language model, DeepSeek-V3, which not only challenges top-tier models like GPT-4 in performance but also achieves breakthrough improvements in generation speed. This represents not just a significant milestone for DeepSeek but also signals the rapidly narrowing gap between open-source and proprietary AI models.
Technical Prowess and Innovation
DeepSeek-V3 employs a proprietary MoE (Mixture of Experts) architecture, boasting 671B total parameters with 37B active parameters during computation. The model has completed pre-training on an impressive 14.8 trillion tokens, demonstrating remarkable scale.
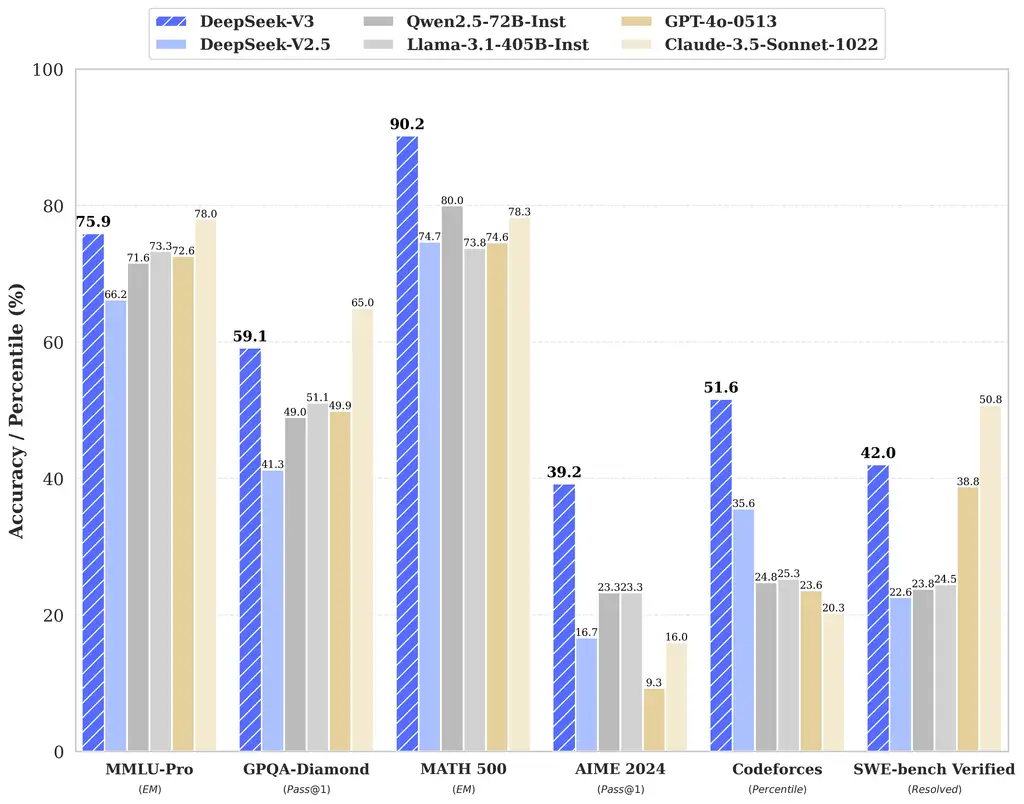
Most notably, this new model has demonstrated exceptional performance across multiple key benchmarks. In areas including knowledge-based Q&A, long-text comprehension, code generation, and mathematical computation, DeepSeek-V3 not only surpasses comparable open-source models but also outperforms industry benchmarks like GPT-4 and Claude-3.5 in certain tests.
Comprehensive Capability Advancement
DeepSeek-V3 shows impressive results across various domains:
- In encyclopedic knowledge, it approaches the performance of the current leader, Claude-3.5-Sonnet
- In programming, particularly algorithmic coding, it significantly outperforms other non-premium commercial models
- Mathematical prowess is a particular highlight, with superior problem-solving capabilities demonstrated in both American Mathematics Competitions and Chinese High School Mathematics Olympiad
- Chinese language processing capabilities are equally noteworthy, matching top-tier models in authoritative C-Eval assessments and even excelling in certain specialized areas
A major breakthrough lies in generation speed. DeepSeek-V3 has achieved a remarkable 3x performance improvement, increasing text generation speed from 20 tokens per second to 60 tokens per second. “This significant advancement ensures users will experience more fluid and natural conversational interactions,” the team notes.
Competitive Pricing Strategy
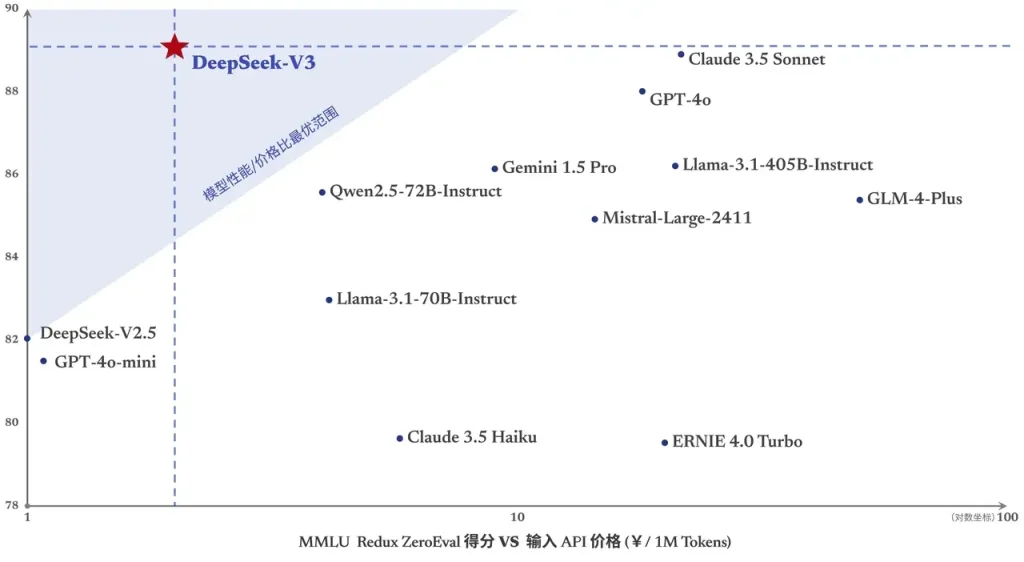
To facilitate broader access to this groundbreaking model, DeepSeek has introduced an extended 45-day promotional period. From now until February 8, 2025, API services will maintain highly competitive rates: as low as 0.1 yuan per million input tokens for cache hits (1 yuan for cache misses), and 2 yuan per million output tokens.
Open-Source Commitment
Demonstrating their commitment to open-source principles, DeepSeek has released the model’s native FP8 weights alongside comprehensive conversion tools. Leading frameworks such as SGLang and LMDeploy have already implemented support, enabling developers to quickly deploy the model in their applications.
Future Vision and Development
The DeepSeek team has outlined an ambitious roadmap for V3’s base model, focusing on developing enhanced capabilities including advanced reasoning and multimodal applications. True to their open-source philosophy, they remain committed to collaborating with the community to advance AI technology.